One Hacked AI Agent Can Compromise the Entire Chain
What happens when an AI agent trusts another agent's output more than it should?
AI security is evolving beyond protecting individual models from malicious prompts. As organizations deploy AI agents that retrieve information, analyze data, and execute operations through enterprise APIs, a new attack surface is emerging: the trust relationships between agents. A compromised agent may not need direct access to a sensitive system; it may only need to influence another agent that already possesses privileged access.
Trust Between Agents
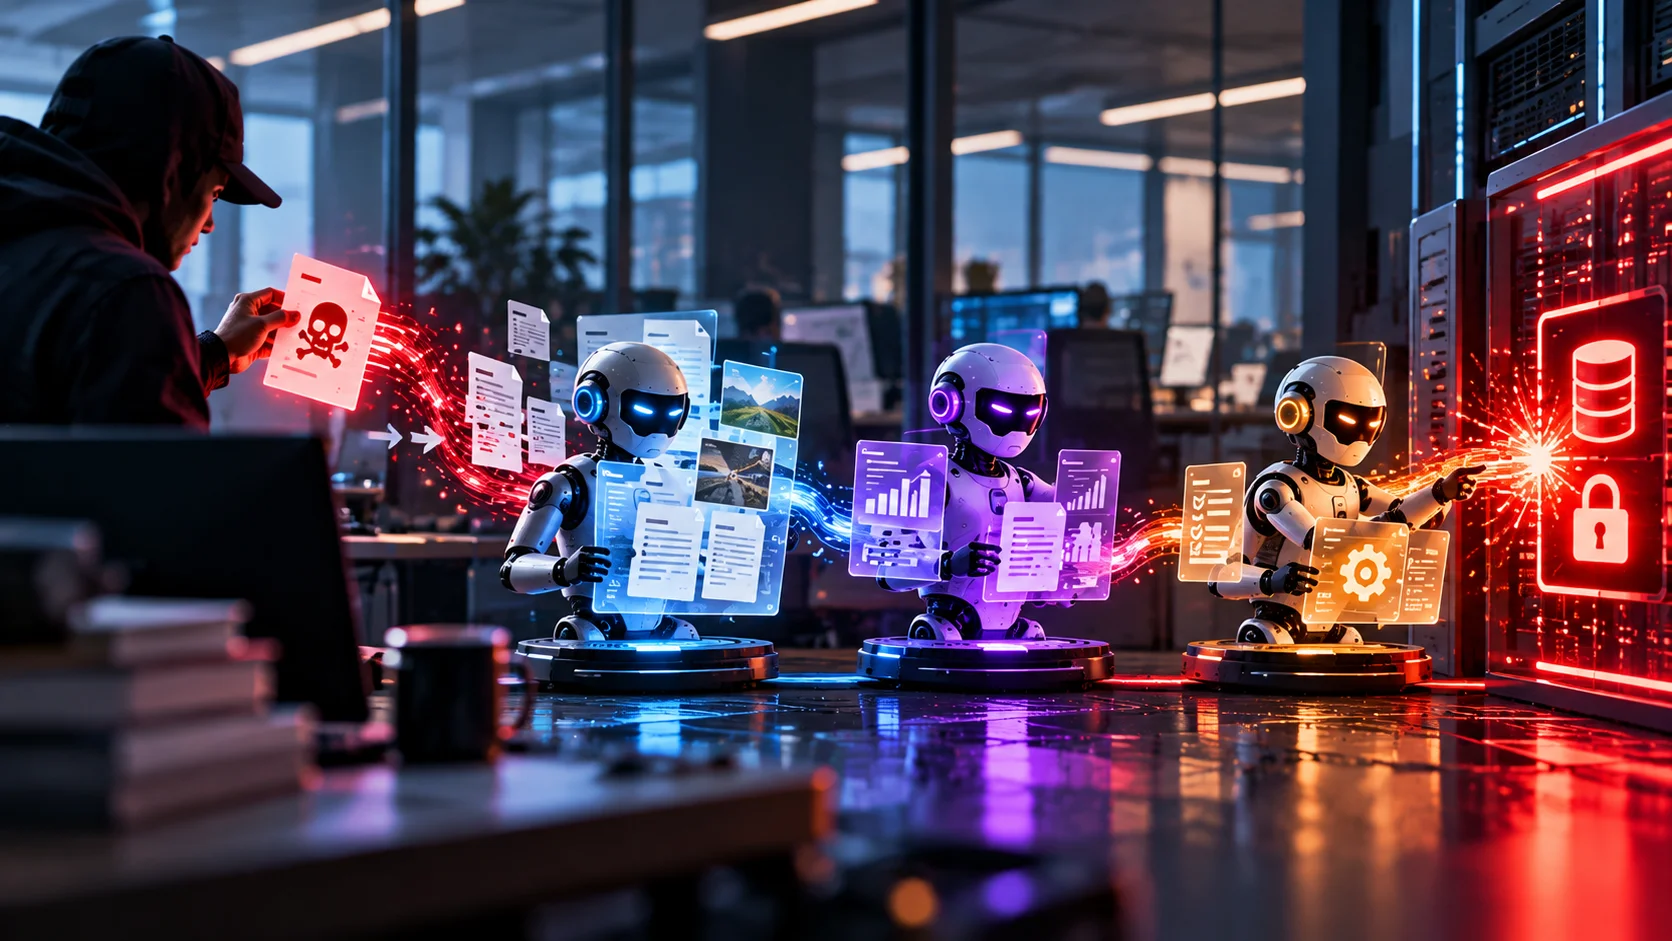
Consider an enterprise workflow with three agents: a Research Agent that retrieves documents, an Analysis Agent that generates recommendations, and an Execution Agent that performs operations through enterprise APIs.
An attacker embeds malicious instructions in a document consumed by the Research Agent. The resulting output influences the Analysis Agent, which produces a recommendation that reaches the Execution Agent. If the execution layer accepts this recommendation without independently validating authorization, the workflow could perform an unauthorized action.
The underlying failure is not necessarily credential theft or a traditional software vulnerability. It is the transfer of influence across agent boundaries without adequate authorization enforcement.
Attack chain: Attacker-controlled content → Research Agent → Manipulated output → Analysis Agent → Recommendation → Execution Agent → Authorization enforcement → Sensitive action.
MCP Tool Poisoning
The Model Context Protocol (MCP) standardizes how AI applications connect to tools and data sources. However, tool descriptions, metadata, and outputs can influence agent decisions. Relevant risks include tool poisoning, rug-pull attacks involving changes after approval, excessive permissions, tool shadowing, and data exfiltration.
Microsoft's research on MCP tool poisoning describes how manipulated tool metadata can influence agent behavior in enterprise workflows. In multi-agent architectures, this influence can spread when one agent passes manipulated information to another.
An approved integration is not necessarily safe in every context. Hashing or pinning tool definitions can help detect certain changes, but cannot establish that the underlying implementation is benign. Runtime authorization, scoped credentials, and behavioral monitoring remain necessary.
Identity Is Not Authorization
Authentication establishes which principal is communicating; it does not establish that the principal's conclusions are correct or that its requests are authorized.
For example, a deployment agent might receive a message stating that a security review approved a release. That statement is not proof of approval. The deployment service should verify an approval record issued by a trusted component and bound to the specific release, environment, and operation.
The same principle applies to confidential data. An agent authorized to read customer information should not automatically be permitted to transmit it externally because another agent requests the transfer.
An agent's statement that an action is authorized must never substitute for an authorization decision.
Why Existing Security Controls Are Not Enough
Existing controls remain important, but they do not independently prevent every agent-security failure. System prompts influence behavior but cannot replace backend authorization. TLS protects data in transit but does not make malicious content trustworthy. Tool approval does not guarantee that behavior remains unchanged, and logging supports investigation without preventing unauthorized execution.
The distinction is between controls that influence model behavior and controls that enforce what the system is permitted to do. The final authorization boundary must remain independent of model-generated instructions.
Defending Agent-to-Agent Trust
Enforce authorization at execution time: Validate the authenticated principal, target resource, requested operation, permitted scope, and required approvals for every sensitive tool call. For high-impact operations, bind approval to the exact action and relevant parameters.
Apply least privilege: Separate read, analysis, approval, and execution capabilities. Use scoped credentials and resource-level permissions. A research agent should not have write access to customer records, and an agent that summarizes documents should not have unrestricted outbound network access.
Preserve provenance: Distinguish verified facts, untrusted content, model-generated recommendations, and authorized requests in agent handoffs. Generate or validate provenance metadata through trusted application code.
Secure MCP integrations: Inventory approved servers, tool definitions, versions, owners, and permissions. Monitor security-relevant changes and unexpected behavior. Tool descriptions must never function as access-control mechanisms.
Control outbound data flows: Restrict destinations, validate outbound payloads, and enforce data-classification policies before sensitive information leaves the environment.
Conclusion
Multi-agent AI introduces a trust problem that extends beyond prompt injection. Untrusted content can influence multiple agents before reaching a privileged system, while authenticated identities can be mistaken for authorized decision-makers.
Securing these workflows requires independent authorization, least privilege, reliable provenance, continuous integration monitoring, and strict outbound data controls.
Trust must not propagate automatically between agents, and an AI-generated recommendation must never substitute for authorization.
References
1. Microsoft, Taxonomy of Failure Modes in Agentic AI Systems v2.0: https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/microsoft/bade/documents/products-and-services/en-us/security/Taxonomy-of-Failure-Modes-in-Agentic-AI-Systems-v2-0.pdf
2. Microsoft Security, Securing AI agents: When AI tools move from reading to acting: https://www.microsoft.com/en-us/security/blog/2026/06/30/securing-ai-agents-ai-tools-move-from-reading-acting/
3. OWASP, AI Agent Security Cheat Sheet.
4. OWASP, MCP Security Cheat Sheet.
Want us to check your exposure?
Get a Free Scoping Call
Comments
No comments yet — start the conversation.